
Automated creative testing uses software to repeat parts of creative preparation, campaign setup, monitoring and reporting. It can reduce repetitive work and make tests easier to review. It does not automatically turn unequal campaign delivery into a controlled experiment or prove that each new creative is better than the last.
Three Different Things Called Creative Testing
| Method | What it can answer | Main limitation |
|---|---|---|
| Pre-launch assessment | Which assets meet a checklist or score well on a model? | A prediction is not a live business result |
| Delivery screening | Which ads look promising under the delivery they received? | Exposure may be unequal and non-random |
| Controlled experiment | Did a defined treatment change the chosen outcome under this design? | Needs suitable assignment, measurement and enough information |
Choose the method before the tool. Ordinary campaign delivery can help screen ideas, but a causal claim needs a suitable experimental design. Google Ads experiments are one native route to investigate for supported campaign types; use the design appropriate to your actual platform and objective.
What Should Be Automated?
Automate work that is repeatable and checkable: linking a brief to approved files, constructing consistent names, preparing supported campaign objects, validating destinations, collecting results and flagging review dates. Keep ownership of the hypothesis, evidence, spending authority and interpretation explicit.
Creative generation, creative scoring, campaign publishing, reporting and post-launch rules can be separate capabilities even when one vendor offers several. A tool described as an automated testing platform may cover only part of that loop.
Step 1: Write a Decision Before Generating Variations
Use this format: “For this audience and offer, we believe changing this creative element will improve this qualified outcome enough to justify the cost.” Name the owner and the decision that follows: reject, revise, retest, scale cautiously or leave inconclusive.
For example, a fictional subscription business could compare a product demonstration with an explanation-led opening while keeping the offer and destination aligned. That is a hypothesis, not a claim that either style is a universal winner.
Step 2: Choose a Metric and an Evaluation Design
Pick a primary metric linked to the business, such as qualified acquisition cost or contribution after acquisition. CTR, views and engagement can diagnose part of the journey, but an ad that attracts more clicks may also attract less suitable customers.
- Define the control, treatment and unit of assignment.
- Decide which differences are intentional and which settings should remain comparable.
- Record the attribution window, conversion lag and any downstream qualification delay.
- Specify the effect that would change the business decision, the acceptable uncertainty and the analysis approach.
- Set a review window and stopping rule before seeing the results.
Equal budgets alone do not establish randomization. Nor does placing several ads inside one ad set. Platform allocation can change who sees an ad and how often it appears, so describe observational results accordingly.
Step 3: Build an Asset and Test Register
| Field | Purpose |
|---|---|
| Test ID and hypothesis | Connect the result to a written question |
| Concept and variant ID | Separate a new idea from a minor edit |
| Approved file and version | Identify exactly what was reviewed |
| Audience, offer and destination | Record the commercial context |
| Platform and native IDs | Connect preparation to created objects |
Keep the original file, approved copy, rights and evidence together. AI-generated content still needs factual, brand and rights review. Do not turn a competitor observation into a copied script, an invented customer quote or an unsupported before-and-after claim.
Step 4: Automate Preparation and Verify the Launch
Use templates or structured inputs for supported names, media, copy, destinations and tracking. Preview each required placement and confirm the account, objective, audience, budget, schedule and launch status before submitting.
After submission, save returned IDs and inspect results in the native platform. A submitted batch can contain a mixture of created objects, rejected items and uncertain operations. Reconcile before retrying so an interrupted workflow does not produce duplicate ads.
AdManage’s bulk launcher and Google Sheets workflow can help with approved creative and repeatable launch preparation. Verify the exact supported channel, object, format and plan. Publishing more variants does not by itself improve the experimental design.
Step 5: Monitor Incidents Separately from Performance Decisions
Broken destinations, incorrect identities, rejected ads, missing measurement or unauthorised spend need prompt attention. A noisy early CPA is a different kind of signal. Use operational alerts to investigate the first group without declaring a performance winner from immature outcomes.
A creative can receive less spend because of delivery allocation rather than because it has been fairly tested and lost. Record that as insufficient exposure or a screening observation where appropriate, not a controlled failure.
Step 6: Evaluate Mature Outcomes and Uncertainty
Choose information requirements from the baseline outcome rate, the effect that matters, the design and the accepted error risk. Impressions are not interchangeable with independent conversion observations. There is no universal 2,000-impression threshold, mandatory 5% CTR gap or three-day test duration.
Frequent checking and stopping at the first favourable result can distort a fixed-horizon analysis. Use the planned analysis, or a suitable sequential approach designed for repeated decisions. Account for multiple comparisons when many variants or metrics are evaluated.
If the result cannot distinguish a useful effect from noise, mark it inconclusive. A tidy dashboard or a confidence label cannot fix unreliable tracking, biased exposure or an outcome that is irrelevant to the business.
Step 7: Keep a Decision Log and Plan the Next Test
| Record | Example question |
|---|---|
| Delivery | Did the intended audience and variants receive usable exposure? |
| Outcome maturity | Have delayed purchases or qualified leads arrived? |
| Effect and uncertainty | How large is the observed difference, and what remains plausible? |
| Commercial meaning | Would the difference matter after costs, returns and capacity limits? |
| Anomalies | Did a promotion, outage or unrelated account change interfere? |
Carry the lesson into the next brief, with its limitations. A winning message in one audience, product or season is evidence for that context, not a permanent creative rule. A new experiment should have its own hypothesis rather than simply generating more variations of the latest winner.
Automated Rules Need Separate Guardrails
A rule that pauses an ad or changes a budget is an operational decision system. Before enabling it, confirm the supported condition, metric window, object scope, action, timing, caps and activity log. Define who investigates an unexpected action and how to reverse it.
Performance-triggered actions are not guaranteed real-time spending caps. Reporting and execution delays can matter. Avoid multiple systems controlling the same setting without an explicit ownership rule, and do not apply one platform’s documented rule behaviour to another.
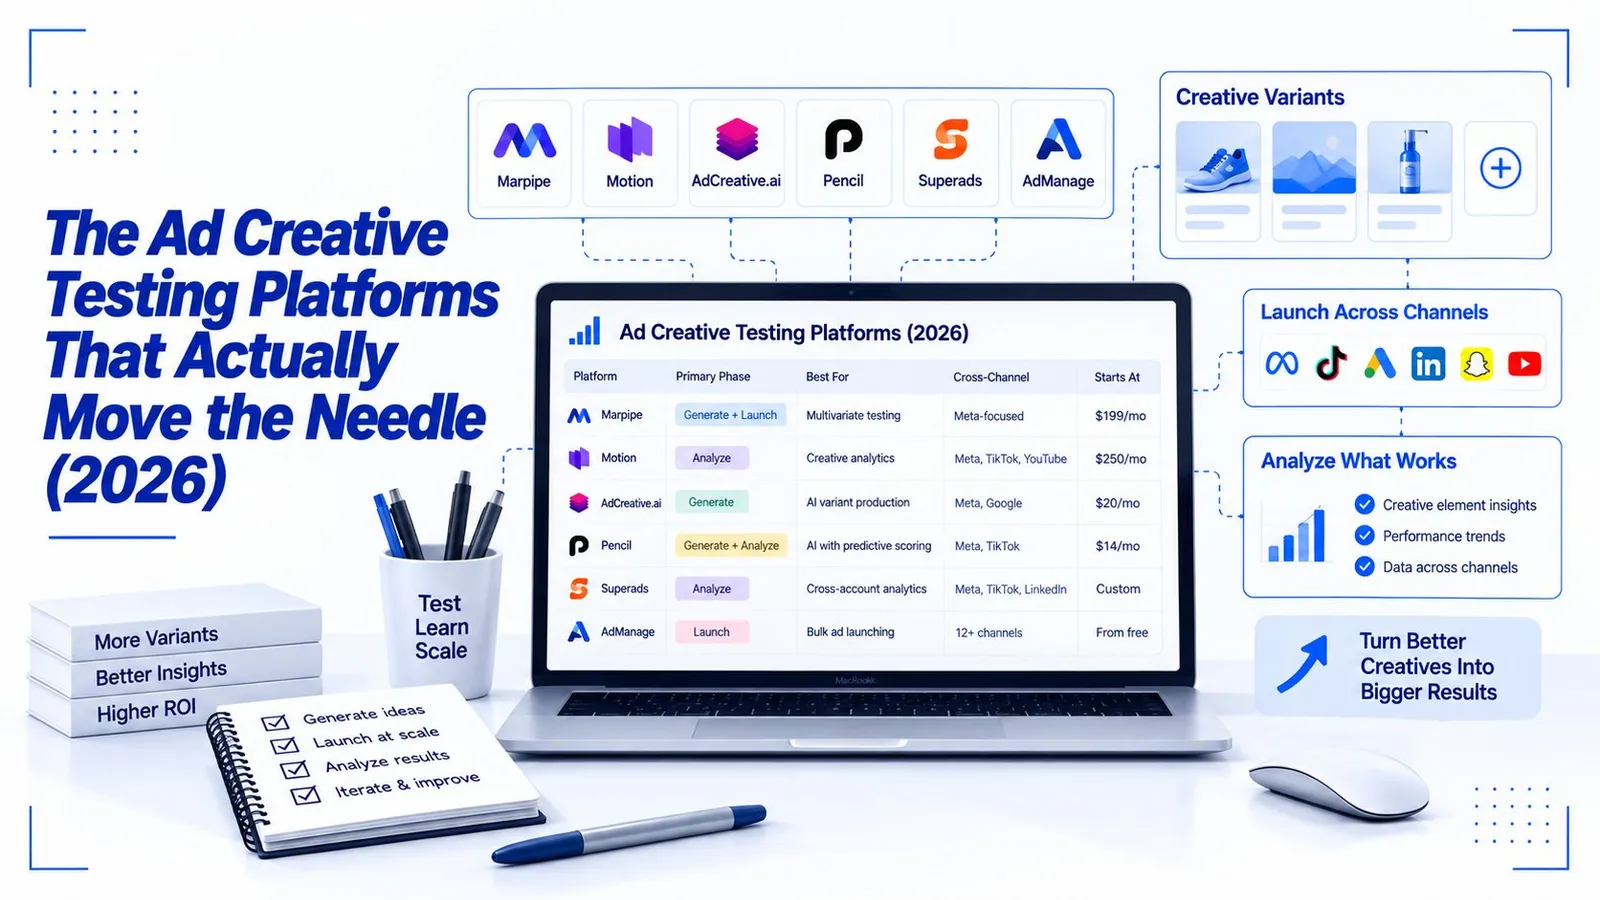
How to Compare Automated Creative Testing Tools
| Capability | Ask the vendor to demonstrate |
|---|---|
| Creative preparation | A real approved asset and required export |
| Campaign operations | Your actual account, format and object creation flow |
| Experiment support | Assignment, control, reporting and limitations |
| Measurement | Metric definition, source, lag and reconciliation |
| Actions | Exact permitted change, guardrail and log |
Use current product documentation and a representative workflow. Avoid a feature checklist that treats prediction, publishing and causal inference as equivalent. Measure preparation efficiency and advertising outcomes separately.
Automated Creative Testing FAQs
How many creative variants should I test?
As many as the design and available information can support. More variants increase the number of comparisons and can divide exposure. There is no universal three-to-five rule.
How long should a test run?
Long enough for the planned information and conversion maturity, while respecting the chosen design and stopping rule. A fixed number of days does not fit every audience, budget or sales cycle.
Can AI predict the winner before launch?
A model can prioritize candidates. Its prediction still needs validation against the live outcome and context that matter to the business.
Can I fully automate the decision?
Some well-defined actions can be automated with suitable controls. Keep an accountable owner for the objective, permissions, evidence quality, exceptions and changes to the decision rule.
Cedric Yarish is a Meta ads expert, performance marketer and product builder with 10+ years of experience across Photoroom, Nextdoor and MVF. At Photoroom, he led user acquisition with more than $1 million in monthly ad spend and a creative operation producing 400 ads a month across 30 languages.
Today, he leads product and engineering at AdManage, the platform he co-founded with his brother Raphael to help marketers launch, test and manage ads at scale. Meta has quoted him on its developer blog and invited him to speak on its Partner API Panel in New York. His insights on creative testing and advertising automation have also featured in RevenueCat and In Growth We Trust.
Full founder bio & interviews